Research
I am an AI Researcher at Descript, working on generative models that power audio and video editing in production. My current focus spans audio codecs, diffusion models and audio-text forced alignment. A full list of papers is on Google Scholar.
Applied Research
Audio Regenerate
Seamless word-level audio editing via latent inpainting.
Video Regenerate and Translation
Audio-driven lip-sync for editing and translation.
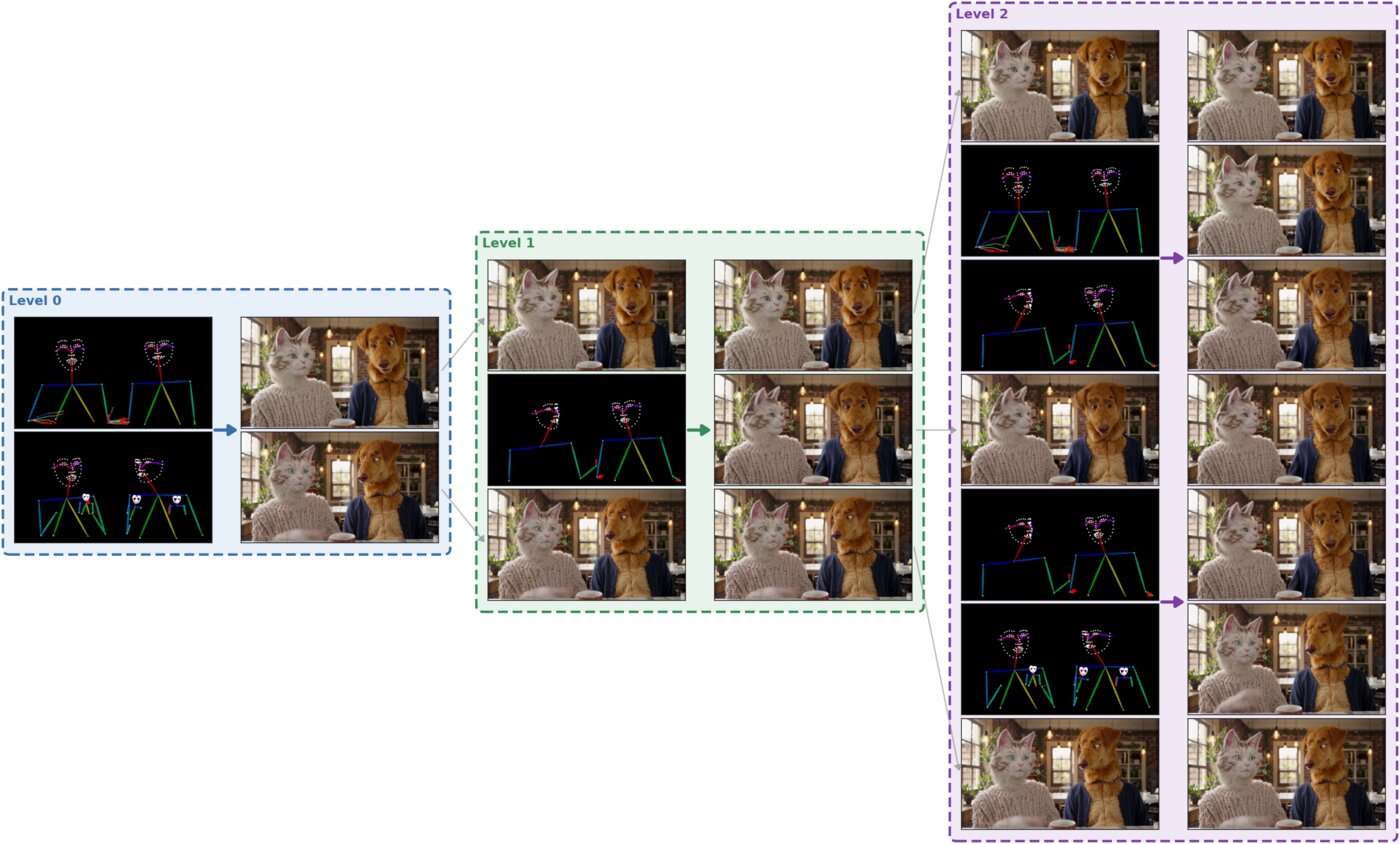
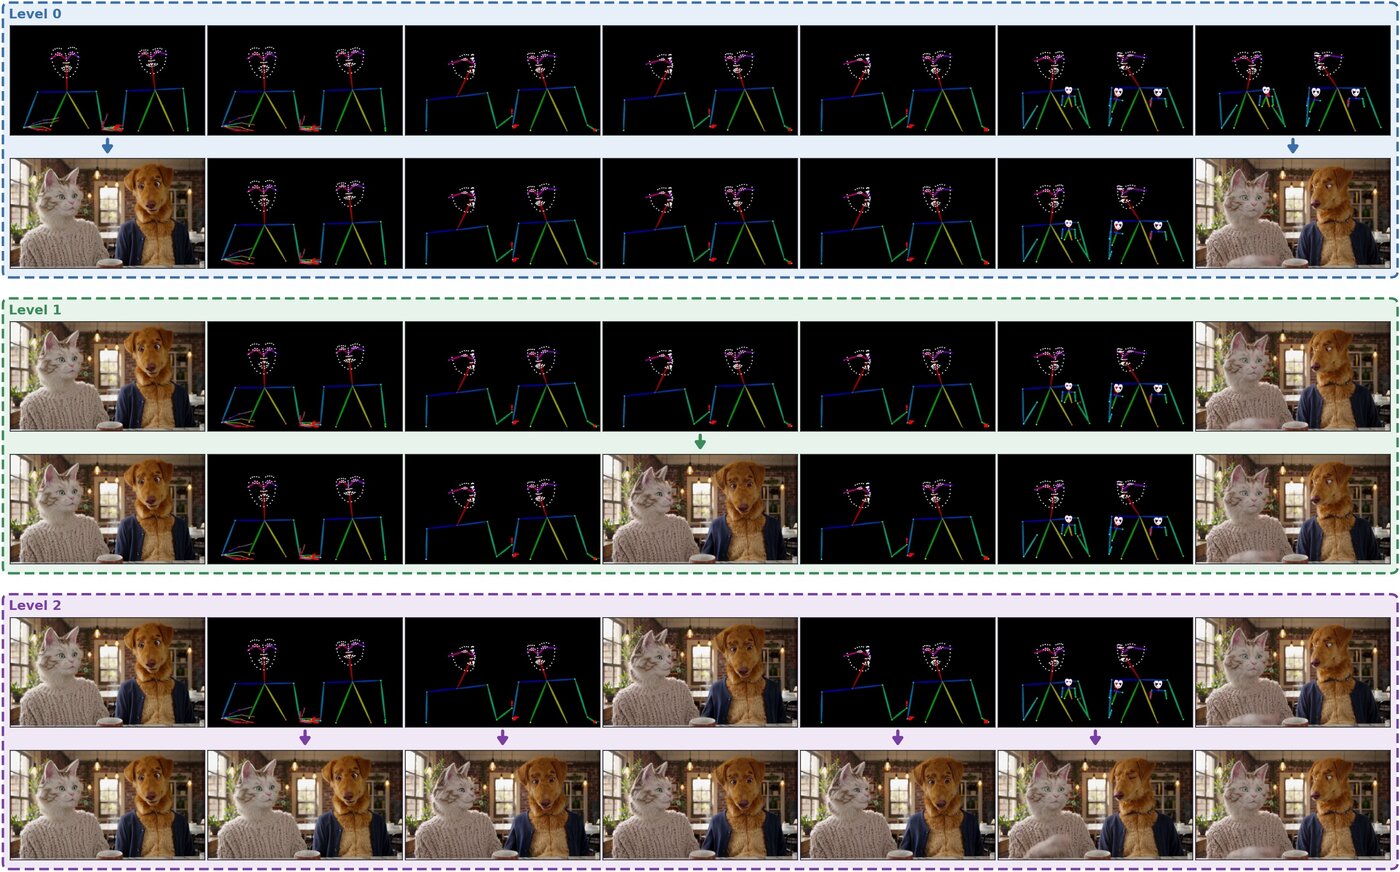
Anchored Tree Sampling
A training-free inference scheduler that replaces autoregressive rollout with sparse-to-dense tree sampling, enabling drift-free long-horizon video-to-video generation.
[project page] [preprint] [code]
Publications & Submissions
-
Goodbye Drift: Anchored Tree Sampling for Long-Horizon Video-to-Video Generation
[preprint] [project page] [code] -
PoDAR: Power-Disentangled Audio Representation for Generative Modeling
[preprint] -
Switching Subspace Model for Neural Population Analysis
[preprint] -
Assessing Comprehensibility of Children’s Read Speech
[preprint] [presentation] [report] -
Deep Learning for Prominence Detection in Children’s Read Speech
[publication] [presentation] [report] -
CNN Encoding of Acoustic Parameters for Prominence Detection
[preprint] [presentation] [report]
Other Research
-
Character Animation from Video in Blender (Honors Project)
[presentation] [report] -
SIRD Model for Studying Outbreak of Infectious Diseases
[report] [code]